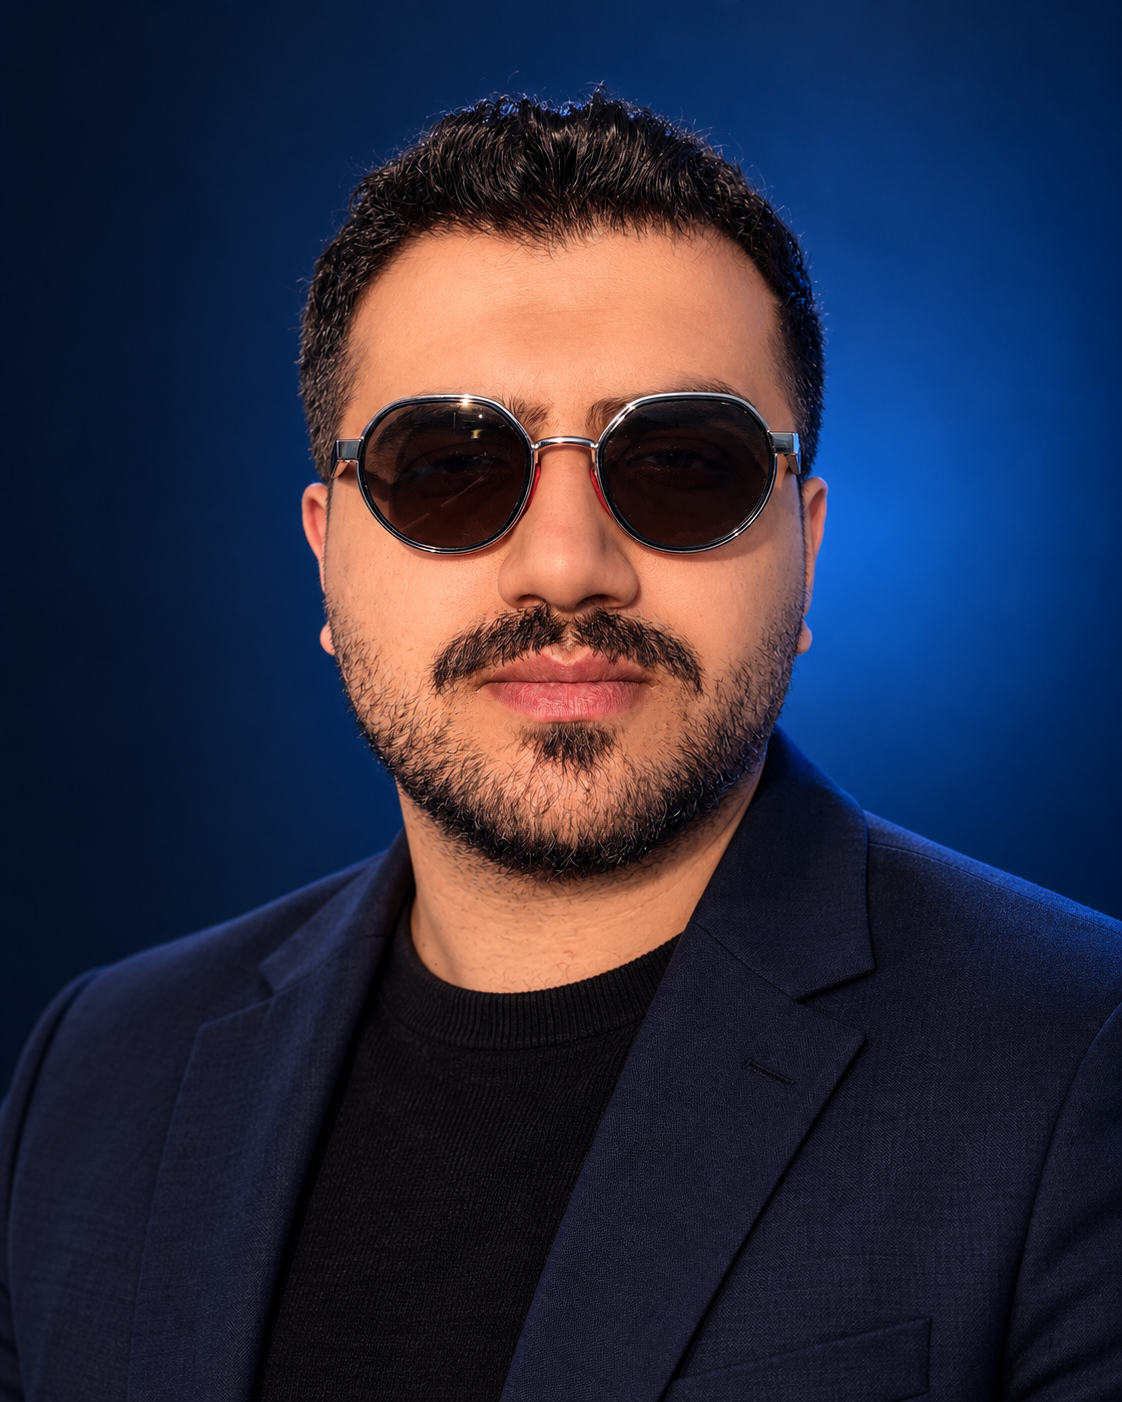
Ali Azmoudeh wearing a navy blazer and sunglasses in a studio-style portrait

PhD Student and Researcher · Computer Vision

Ali
Azmoudeh.

I develop computer vision systems that remain reliable when data is limited, synthetic, or shifted.

Istanbul Technical University · SiMiT LabScroll to discover
AI-styled portrait

One question. Three connected directions.

From seeing.
To understanding.

How can a model generalize responsibly when the real world does not match its training set?

MULTIMODAL VISION / 02VISUAL + LANGUAGE
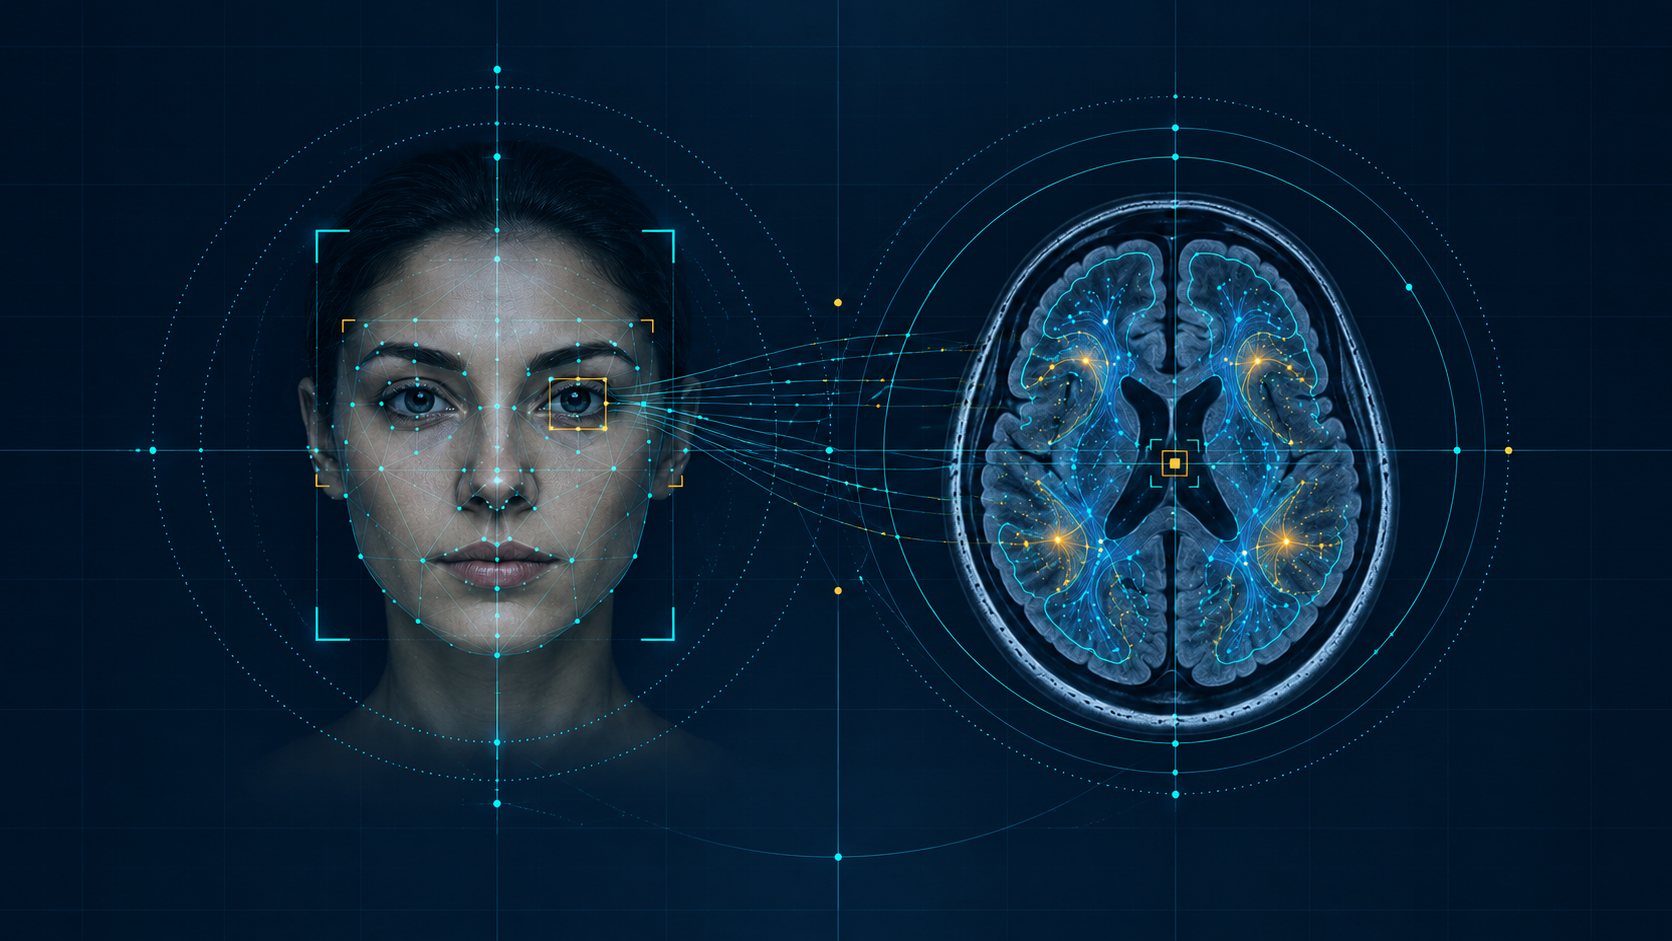
Wide conceptual illustration of a complete face and brain MRI linked by visual analysis connections
FACEvisual analysis
BRAINmedical imaging
VISION–LANGUAGEmultimodal reasoning

Research imagery is conceptual, not experimental output.

Conceptual translucent brain above layered MRI-like slices

Medical image analysis

Reliable vision.
When it matters.

Brain MRI segmentation across high- and low-quality imaging domains.

Beyond clean benchmarks

Different data.
The same responsibility.

I explore transfer learning, ensemble models, and conformal risk control to study reliability under domain shift.

Medical imagingDomain shiftUncertainty
Conceptual synthetic faces with subtle expression variations and facial landmarks

Facial analysis & synthetic data

Expressions.
New perspectives.

Understanding expressions through real and synthetic visual data.

Learning from generated data

More possibilities.
Thoughtful evaluation.

Privacy-aware facial expression recognition and text-guided expression generation using vision-language and generative models, synthetic data, and cross-dataset evaluation.

Facial expressionsSynthetic dataGenerative models
Conceptual visual and language representations connected through shared layers

Multimodal visual understanding

Images meet
language.

Connecting what a model sees with what language means.

Visual + language

Different modalities.
Shared understanding.

Vision-language models and visual-textual cross-attention for multimodal reasoning, including IMMCAN idiom understanding and open-world text-guided visual counting.

Vision–language modelsCross-attentionVisual counting

Selected publications

Ideas into
contributions.

Peer-reviewed work and open research across medical vision, facial analysis, multimodal reasoning, and visual counting.

P / 04

VisAffect at MWE-2026 AdMIRe 2: IMMCAN Idiom Multimodal Cross-Attention Network

22nd Workshop on Multiword Expressions · ACL, 2026 · pp. 149–153

Integrates visual and textual representations through multimodal cross-attention for idiom understanding and multimodal reasoning.

P / 03

On Applicability of Synthetic Datasets for Facial Expression Recognition

IEEE FG 2026 · Kyoto, Japan · First author

Examines pseudo-labeling, diffusion-based synthesis, and GAN-based expression editing as privacy-preserving ways to address imbalance and limited facial-expression data.

P / 02

GLIMS-MedNeXt: An Ensemble Framework for Brain MRI Segmentation in Sub-Saharan Africa

MICCAI 2025 BraTS-Lighthouse · LNCS 16376 · Springer, 2026

Combines GLIMS and MedNeXt with transfer learning and ensemble fusion to improve brain-tumor segmentation under low-quality imaging conditions.

P / 01

A Survey on Class-Agnostic Counting: Advancements from Reference-Based to Open-World Text-Guided Approaches

Computer Vision and Image Understanding · 2026 · Article 104703

Introduces a taxonomy spanning reference-based, reference-less, and open-world text-guided counting, and reviews 29 approaches on established benchmarks.

Behind the research

Curiosity.
Learning.
Problem solving.

I am a PhD student in Computer Engineering at Istanbul Technical University and a Graduate Research Assistant at SiMiT Lab, working under the supervision of Prof. Dr. Hazım Kemal Ekenel.

My research sits at the intersection of computer vision, deep learning, and trustworthy AI. I study how vision models behave beyond clean benchmarks: under domain shift, limited annotations, low-quality medical scans, privacy constraints, and imbalanced data.

Current directions include reliable brain-tumor MRI segmentation, conformal risk control, vision-language-guided facial expression generation, multimodal idiom understanding, and class-agnostic visual counting.

I am enthusiastic about exploring emerging ideas, continuously expanding my knowledge, and applying what I learn to solve challenging real-world problems.
Based
Istanbul, Türkiye
Affiliation
ITU · SiMiT Lab
Role
PhD Student and Researcher · RA/TA
Advisor
Prof. Dr. Hazım Kemal Ekenel
Focus
Computer Vision · Multimodal AI · Trustworthy Medical AI

Research & education

The path so far.

2025—

PhD, Computer Engineering

Istanbul Technical University · Computer vision and trustworthy medical AI

2024—

Turkcell Graduate Research & Teaching Assistant

Istanbul Technical University · Research and undergraduate teaching

2022—

Graduate Research Assistant

SiMiT Lab, ITU · Computer vision, biometrics, and medical imaging

2022–25

MSc, Computer Engineering

Istanbul Technical University

2016–21

BSc, Computer Engineering

University of Tabriz

Research collaboration

Let’s build vision systems that generalize.

For research discussions, collaborations, or questions about my published work, reach me through my ITU email.

Start a conversation